Building
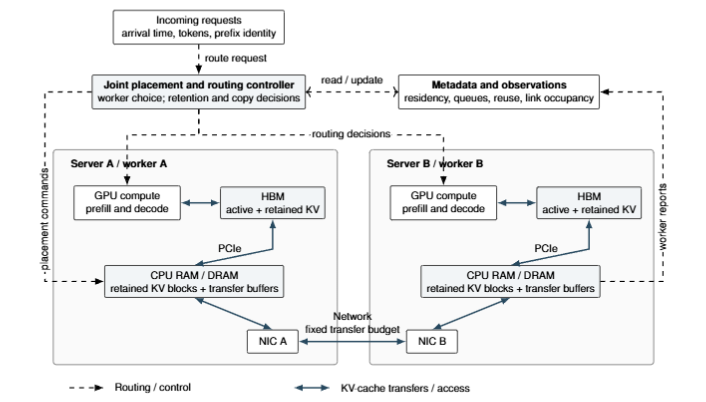
currently building efim1: LLM Inference Optimization (KV Cache and Context Reuse)
-
Found that LMCache KV reuse produced divergent outputs across four NVIDIA T4/L4 tests despite reporting cache hits, while vLLM's native prefix cache stayed exact, and released a standalone KV-cache correctness verifier. Building efim1 with two other UWaterloo students and leading a seven-person inference research team, exploring proof-carrying inference as the longer-term direction.
-
SEP-1: A Sole-Egress Package-Broker Profile for Model-Evaluation Sandboxes
Apart Research AI Incident Response SprintA sandbox containment standard motivated by the OpenAI→Hugging Face incident, which escaped via a package-registry proxy. SEP-1 swaps network allowlists for a socket to a hash-pinned package broker, containing 11 of 12 attacks vs. 1 of 12 under an allowlist.
-
Compute Governance Observatory · AI Compute Capacity & Policy Research with BlueDot Impact
Researching global AI compute capacity and analyzing specific public LLM training runs and clusters. Implemented regulatory-threshold comparisons (EU AI Act) and cross-country/company compute capacity analysis with adjustable efficiency assumptions.
-
AAOS · AI Operating System & Research Platform
Built a custom 32-bit x86 kernel in C and Assembly, booted in QEMU and linked to an LLM through a Python COM1 serial bridge, alongside a Next.js/FastAPI research platform with streaming AI responses.
-
Sidereus · AI-Native Equity Research
Built an AI-native equity research platform with specialized agents for SEC filings, earnings calls, valuation, and competitive analysis, generating investment reports on individual companies.
-
World.io · First-Person Trading Office Environment
A 3D office environment with a 360° panorama renderer and an embedded stock market terminal — live quotes, watchlists, and historical charts backed by server-only Next.js route handlers.
-
Mini HFT System · Low-Latency Trading Simulator
Engineered a C++20/Python matching engine with a swappable HAL achieving 1.2µs p50 latency and 748K resting orders/sec, plus a Next.js dashboard streaming order-book depth, trade tape, and strategy P&L over WebSockets.